
Three weeks, two Claude models, two cheaper GPT-6 tiers, a $30 billion funding talk, and a model from Xiaomi that quietly set a new bar for open weights. That’s the short version of what happened in AI between roughly September 10 and October 1, 2026. This is the direct follow-up to last month’s roundup, and if that one was about labs figuring out how to survive a price war, this one is about what happens once everyone’s already in it: you start competing on things other than the scoreboard.
Key Takeaways
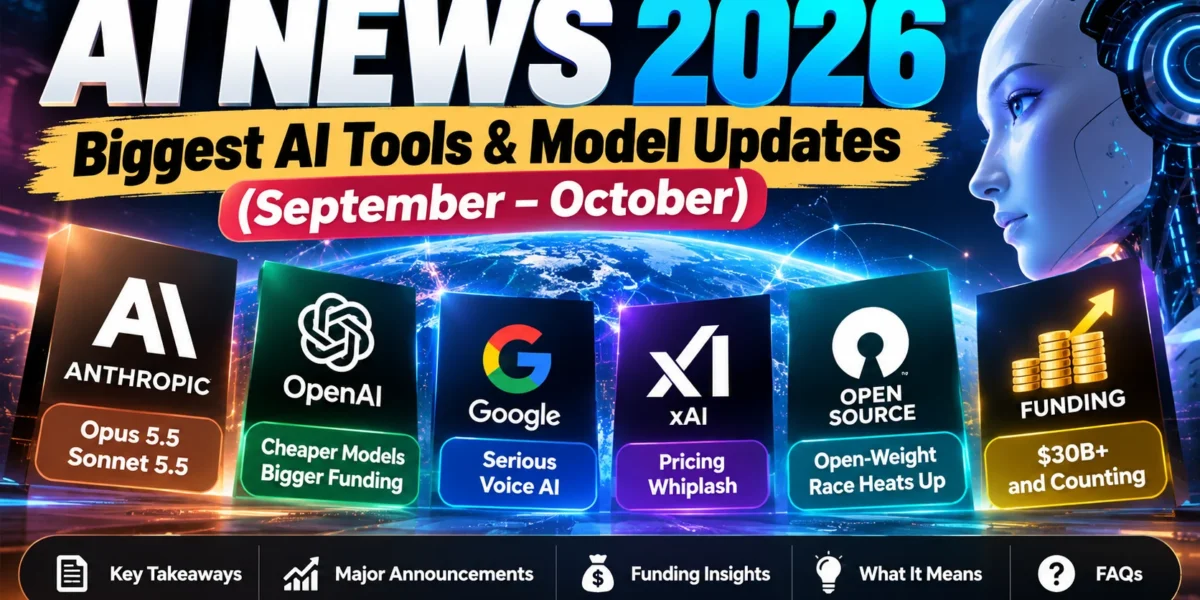
- Anthropic shipped two flagship refreshes in six days — Claude Opus 5.5 (Sept 22) and Claude Sonnet 5.5 (Sept 28) — both cheaper and faster than the models they replace.
- OpenAI answered the same week with GPT-6 Sol and GPT-6 Luna, two mid-tier and budget models priced at half of what their predecessors cost, while reportedly lining up a $30 billion funding round at a $1.4 trillion valuation.
- Google quietly turned Gemini into a serious voice-AI platform with Gemini 3.8 Flash TTS and Flash-Lite TTS, which now top the independent Hume AI voice-quality leaderboards.
- xAI dropped a cheaper Grok 4.7 for developers even as parent company SPCX floated an overhaul of Grok and X subscription pricing — a sign of where the financial pressure actually sits.
- The open-weight field got more crowded and more efficient: Xiaomi’s MiMo v2.6 posted the highest benchmark score ever recorded for an open-weight model, and Cohere open-sourced a frontier-class model for the first time in years.
- Mistral closed Europe’s largest-ever AI funding round (around $3.5 billion), underlining that the money chasing this industry hasn’t slowed down even as prices for using it keep falling.
Anthropic’s One-Two Punch: Opus 5.5, Then Sonnet 5.5
If you only read one section of this roundup, make it this one. On September 22, Anthropic released Claude Opus 5.5, and six days later, on September 28, it followed up with Claude Sonnet 5.5. Shipping two flagship-tier refreshes inside a single week isn’t normal, even by 2026 standards, and it tells you Anthropic wanted this quarter to be about Claude rather than about whoever had the loudest headline that week.
Opus 5.5 is priced about 20% below Opus 5 on both input and output tokens ($4 and $20 per million, respectively), with cache reads down 60% to $0.20 per million. Anthropic says that works out to roughly 40% lower cost on a typical real-world workload, because the model also tends to use fewer tokens to finish the same job. On benchmarks, it posted 66.4% on Terminal-Bench 4.0 (up from Fable 5.1’s 55.8%), edged out GPT-6 Astra on FrontierCode v1.1, and beat GPT-5.6 Sol by 11 points on CursorBench 4.0. One detail that stuck with us: Anthropic says a tester used it to complete a 680,000-line code migration in under a day — the kind of job that would normally eat an engineering team’s sprint.
Sonnet 5.5 is the more interesting release for most people reading this, honestly, because Sonnet is the tier most developers and everyday Claude users actually live in. The pricing hasn’t changed from Sonnet 5 ($2 input / $10 output per million tokens), but Anthropic says it runs about 30% faster and typically costs up to 30% less in practice simply because it burns through fewer tokens to get to the same answer. The bigger shift is under the hood: Sonnet 5.5 is the first model at that tier to carry cybersecurity safeguards comparable to Anthropic’s flagship models, which matters given how much scrutiny that capability has drawn industry-wide (we covered the broader trend toward restricted “cyber” models in our explainer on what Google, OpenAI, and Anthropic’s cyber models actually do). Fittingly, Anthropic is routing most cybersecurity-flavored tasks on Opus 5.5 to the older Opus 4.8 instead, and keeping full access behind its Cyber Verification Program for vetted practitioners.
Put plainly: Anthropic used this stretch to make its two most-used models both cheaper and meaningfully better at coding and agentic work, and it did it faster than OpenAI or Google managed to respond. That’s a real competitive flex, not just a version bump.
OpenAI’s Answer: Cheaper Models, and a Much Bigger War Chest
On the exact same day Anthropic shipped Opus 5.5 — September 22 — OpenAI released GPT-6 Sol and GPT-6 Luna, two tiers built to sit underneath GPT-6 Astra rather than replace it. Luna is the cheap, high-volume option: $0.10 per million input tokens and $0.50 per million output, which is roughly half of what the previous Luna tier cost and undercuts most rivals on simple jobs like summarizing or extracting data. Sol sits a step up at $2 and $10 per million tokens — exactly half of its predecessor’s price, and, notably, the same rate Anthropic charges for Sonnet 5. OpenAI says Sol now makes about half as many factual errors as the model it replaces and is closing in on “Astra-level” reliability, while costing roughly 80% less per task on computer-use benchmarks like OSWorld 2.0.
The positioning is straightforward once you see it: Luna for the simple, repetitive stuff you run thousands of times a day; Sol for the recurring complex work — feature-building, code review, debugging, data analysis; and Astra held in reserve for the jobs that genuinely need the best model money can buy. It’s the same tiered playbook every lab is now running, and it only works if the cheap tier is actually good enough that developers don’t feel like they’re settling.
Here’s where it gets interesting, though. Within a week of cutting prices across its API, Bloomberg and TechCrunch reported that OpenAI is in talks to raise at least $30 billion in new funding at a $1.4 trillion valuation — up from the $852 billion valuation it carried after its $122 billion round back in March. That March round was supposed to be the company’s last stop before going public. Instead, the IPO has reportedly slipped to 2027, and this new raise is being described as bridge financing to get there. For context on why investors are still this eager despite OpenAI slashing its own prices: the company’s revenue run-rate reportedly grew 70% since July, hitting roughly $40 billion a month by August, largely on the back of coding-focused usage. Cutting prices while quietly needing tens of billions more in cash isn’t a contradiction, exactly — it’s just what scaling a business this expensive actually looks like from the inside.
Google Quietly Becomes a Serious Voice-AI Company
Away from the model-vs-model scoreboard, Google spent late September building out a part of the stack most people don’t think about until it’s suddenly everywhere: voice. On September 23, it released Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, a pair of text-to-speech models built for very different jobs. Flash TTS is aimed at creative, character-driven work — designing a voice from scratch with a plain-language prompt, directing line-by-line delivery, scripting in vocal effects. Flash-Lite is the cheaper, high-volume sibling, meant for dubbing and voice agents that need to run at scale rather than win an award.
The headline numbers are genuinely impressive: over 2,000 ready-to-use voices, support for more than 100 languages and dialects, and the ability to clone a voice from a 30-second sample (with consent verification built in, to Google’s credit). On Hume AI’s independent Voice Design Benchmark, Flash TTS came out on top with a score of 71.4, and the pair took the first two spots on Hume’s Overall Quality Index. Every clip carries Google’s SynthID watermark, baked in at the audio level so AI-generated speech stays detectable even after it’s been downloaded, edited, or reposted somewhere else.
Google hasn’t published pricing yet, which is a little unusual for a Gemini release, but the rollout plan is already in motion: developers get access now through the Gemini API and AI Studio, enterprise access is coming through the Gemini Enterprise API, and regular users will see it show up inside Gemini Notebook and Google Vids. If you work in media, localization, or customer support and haven’t tested this yet, it’s worth a look — voice is the one modality where the gap between “technically impressive” and “actually sounds human” has closed faster than almost anyone expected.
xAI’s Pricing Whiplash
xAI — which, as we noted last month, now trades publicly as SPCX — released Grok 4.7 on September 21: a 500,000-token context window tuned specifically for coding and knowledge work, priced at roughly $3.20 and $9.60 per million input and output tokens. It’s a solid, unglamorous mid-cycle release, the kind of thing that would barely register on its own.
What makes it worth mentioning is what happened nine days later. On September 30, multiple outlets reported that SPCX is considering consolidating its tangled mess of Grok and X subscription tiers — which currently range anywhere from free to $300 a month for Grok and $3 to $40 for X — into a simpler four-tier structure: a limited free plan, an $8-a-month “Lite” tier bundling Grok access with a verified checkmark, and a $100-a-month “Ultra” tier for full access to what the company is calling Grok Bot AI. Read those two stories together and the picture gets a little clearer: cutting API prices to keep developers from leaving is one thing, but restructuring your entire consumer subscription stack nine days later is the move of a company under real pressure to find a path to profitability. SPCX’s own numbers back that up — a reported operating margin around negative 17%, against a share price trading at well over 150 times sales. The market is pricing in a lot of future growth that hasn’t shown up yet.
The Open-Weight Race Keeps Getting More Interesting
This is the section that would have been impossible to write eighteen months ago, and it’s quietly become the most competitive corner of the whole industry. On September 21, Xiaomi released its MiMo v2.6 family — a Flash, Pro, and Pro-UltraSpeed tier ranging from $0.14 to $4.35 per million tokens — and the Pro tier scored 46 on the Artificial Analysis Intelligence Index, the highest mark ever recorded for an openly licensed model at the time of release. It’s a 1.02-trillion-parameter mixture-of-experts model with only 42 billion active at once, a 1-million-token context window, and an MIT license, which means anyone can take it and build on it commercially with essentially no strings attached.
It wasn’t alone. Z.ai open-weighted GLM-5.3 FlashX on September 18 at a flash-tier price with a full 1-million-token context, and Alibaba followed on September 23 with Qwen3.8 Max Prime, a throughput-optimized variant that it claims runs 1.5 to 2 times faster than the standard Qwen3.8 Max. If you’ve been following along since our piece on DeepSeek V4.1 Flash earlier this month, this is the same story continuing: Chinese labs aren’t just matching Western frontier models anymore on isolated benchmarks, they’re iterating faster and shipping more often, and the gap at the efficient end of the market has basically closed.
The most surprising open-weight move of the month, though, came from a company that almost never does this: Cohere released Command A+ as open source on September 22, with a 192,000-token context window and pricing around $0.30 and $1.50 per million tokens for anyone who’d rather run it hosted than self-host it. Cohere has spent most of the last few years focused on enterprise contracts rather than open releases, so this feels like a signal that even the more conservative labs now see open-weighting as a distribution strategy rather than something to avoid.
Two smaller releases are worth a mention if you’re the type who likes the weird, interesting edges of this field rather than just the leaderboard-toppers. Mercury 2, from Inception Labs, uses non-autoregressive diffusion decoding instead of the usual token-by-token generation, which lets it hit roughly 1,009 tokens per second on Nvidia’s Blackwell chips — genuinely fast, with schema-aligned JSON output baked in, which is exactly what you want for high-throughput structured data work. And Prism ML’s Ternary Bonsai 2, a 27-billion-parameter model squeezed down to a 5.9-gigabyte file using 1.76-bit quantization, somehow keeps 98.2% of its full-precision benchmark performance. If you’ve ever wanted a genuinely capable model running on a laptop with no GPU to speak of, this is the kind of research that gets you there. If you want to go further down that road yourself, we rounded up dozens of self-hostable options in our open-source alternatives guide.
Money Still Talks: The Funding Picture
We already touched on OpenAI’s reported $30 billion raise above, but it wasn’t the only huge check written in AI this month. Early in September, Mistral closed a roughly $3.5 billion Series D led by Samsung, pushing its valuation to somewhere around $23-24 billion and making it the largest AI funding round Europe has ever produced. For a company that’s spent the last two years being described as “Europe’s answer to OpenAI,” that’s a meaningful vote of confidence, and it buys Mistral the compute budget to actually compete on training runs rather than just on efficiency tricks.
Mistral’s CEO used the moment to take a swing at the US side of the AI safety conversation, suggesting in a CNBC interview late in the month that a lot of the public safety debate was doing more to distract from competitors’ own shortcomings than to actually make these systems safer. Whether or not you buy that framing, it’s a reminder that the funding story and the safety story in this industry are never really separate conversations — they’re the same conversation, told from whichever angle benefits the person talking.
Zoom out and the pattern across both of these raises is the same: the price of actually using AI keeps falling, quarter over quarter, and the amount of money willing to bet on the companies building it keeps going up anyway. Those two trends look contradictory until you remember that in this industry, falling prices are usually a sign of a company trying to lock in market share before the next funding round, not a sign that the business is getting less valuable.
What This Month Actually Tells Us
Put the whole three weeks side by side and a pattern falls out pretty cleanly. Nobody’s winning on raw intelligence scores anymore, because the top handful of models are all within a few points of each other on most benchmarks that matter. So the competition has shifted to three things instead: who’s cheapest for the 90% of work that doesn’t need a frontier model, who’s fastest to ship a tier that’s good enough, and who can win on something benchmarks don’t measure at all — voice quality, safety tooling, developer trust, or just having the cash reserves to outlast everyone else in a price war that shows no sign of ending.
If you’re actually using these tools day to day rather than just reading about them, the practical takeaway is simple: whatever you were paying for AI in August is almost certainly too much today, for most of what you’re probably doing with it. Check whether a cheaper tier from your existing provider now matches what you were using a frontier model for a month ago. More often than not in September 2026, the answer was yes.
Frequently Asked Questions
What was the single biggest AI announcement between mid-September and early October 2026?
It depends on what you weight most heavily. For day-to-day usage, Anthropic shipping both Claude Opus 5.5 and Sonnet 5.5 within six days of each other is the biggest story. For the business side of the industry, OpenAI’s reported talks to raise $30 billion at a $1.4 trillion valuation arguably matters more long-term.
What’s the actual difference between GPT-6 Sol, GPT-6 Luna, and GPT-6 Astra?
Luna is OpenAI’s cheapest, highest-volume tier, built for simple repeated tasks like summarizing or extracting data. Sol sits above it for recurring complex work like coding, debugging, and analysis, priced at $2/$10 per million tokens. Astra remains the flagship, reserved for the hardest jobs where raw capability matters more than cost.
Is Claude Opus 5.5 actually cheaper than Opus 5?
Yes. Listed per-token pricing is about 20% lower on input and output, cache reads are 60% cheaper, and Anthropic says real-world workloads typically cost around 40% less overall because the model also uses fewer tokens to complete the same task.
Why is OpenAI raising $30 billion if it’s already valued at over a trillion dollars?
Reporting describes the round as bridge financing to cover the gap after OpenAI pushed its planned IPO back from 2026 to 2027. The company’s revenue has reportedly grown quickly, but running and training frontier models at this scale is extremely capital-intensive, and investors are still willing to fund that growth ahead of a public listing.
What’s the best open-weight AI model right now?
There isn’t a single answer because it depends on your priority. Xiaomi’s MiMo v2.6 Pro currently holds the highest Artificial Analysis Intelligence Index score ever recorded for an open-weight model, but DeepSeek, GLM-5.3 FlashX, and Qwen3.8 Max Prime are all strong depending on whether you care most about raw benchmark performance, context length, or running cost.
Sources: Anthropic — Introducing Claude Opus 5.5, 9to5Mac — Anthropic upgrades Claude with new Sonnet 5.5 model, VentureBeat — OpenAI releases GPT-6 Sol and Luna models, Bloomberg — OpenAI targets $30 billion in new funding, Google — Gemini 3.8 Flash TTS and Flash-Lite TTS, and CNBC — Mistral bags $24 billion valuation as Samsung leads funding.